A crawler that reads what other crawlers skip.
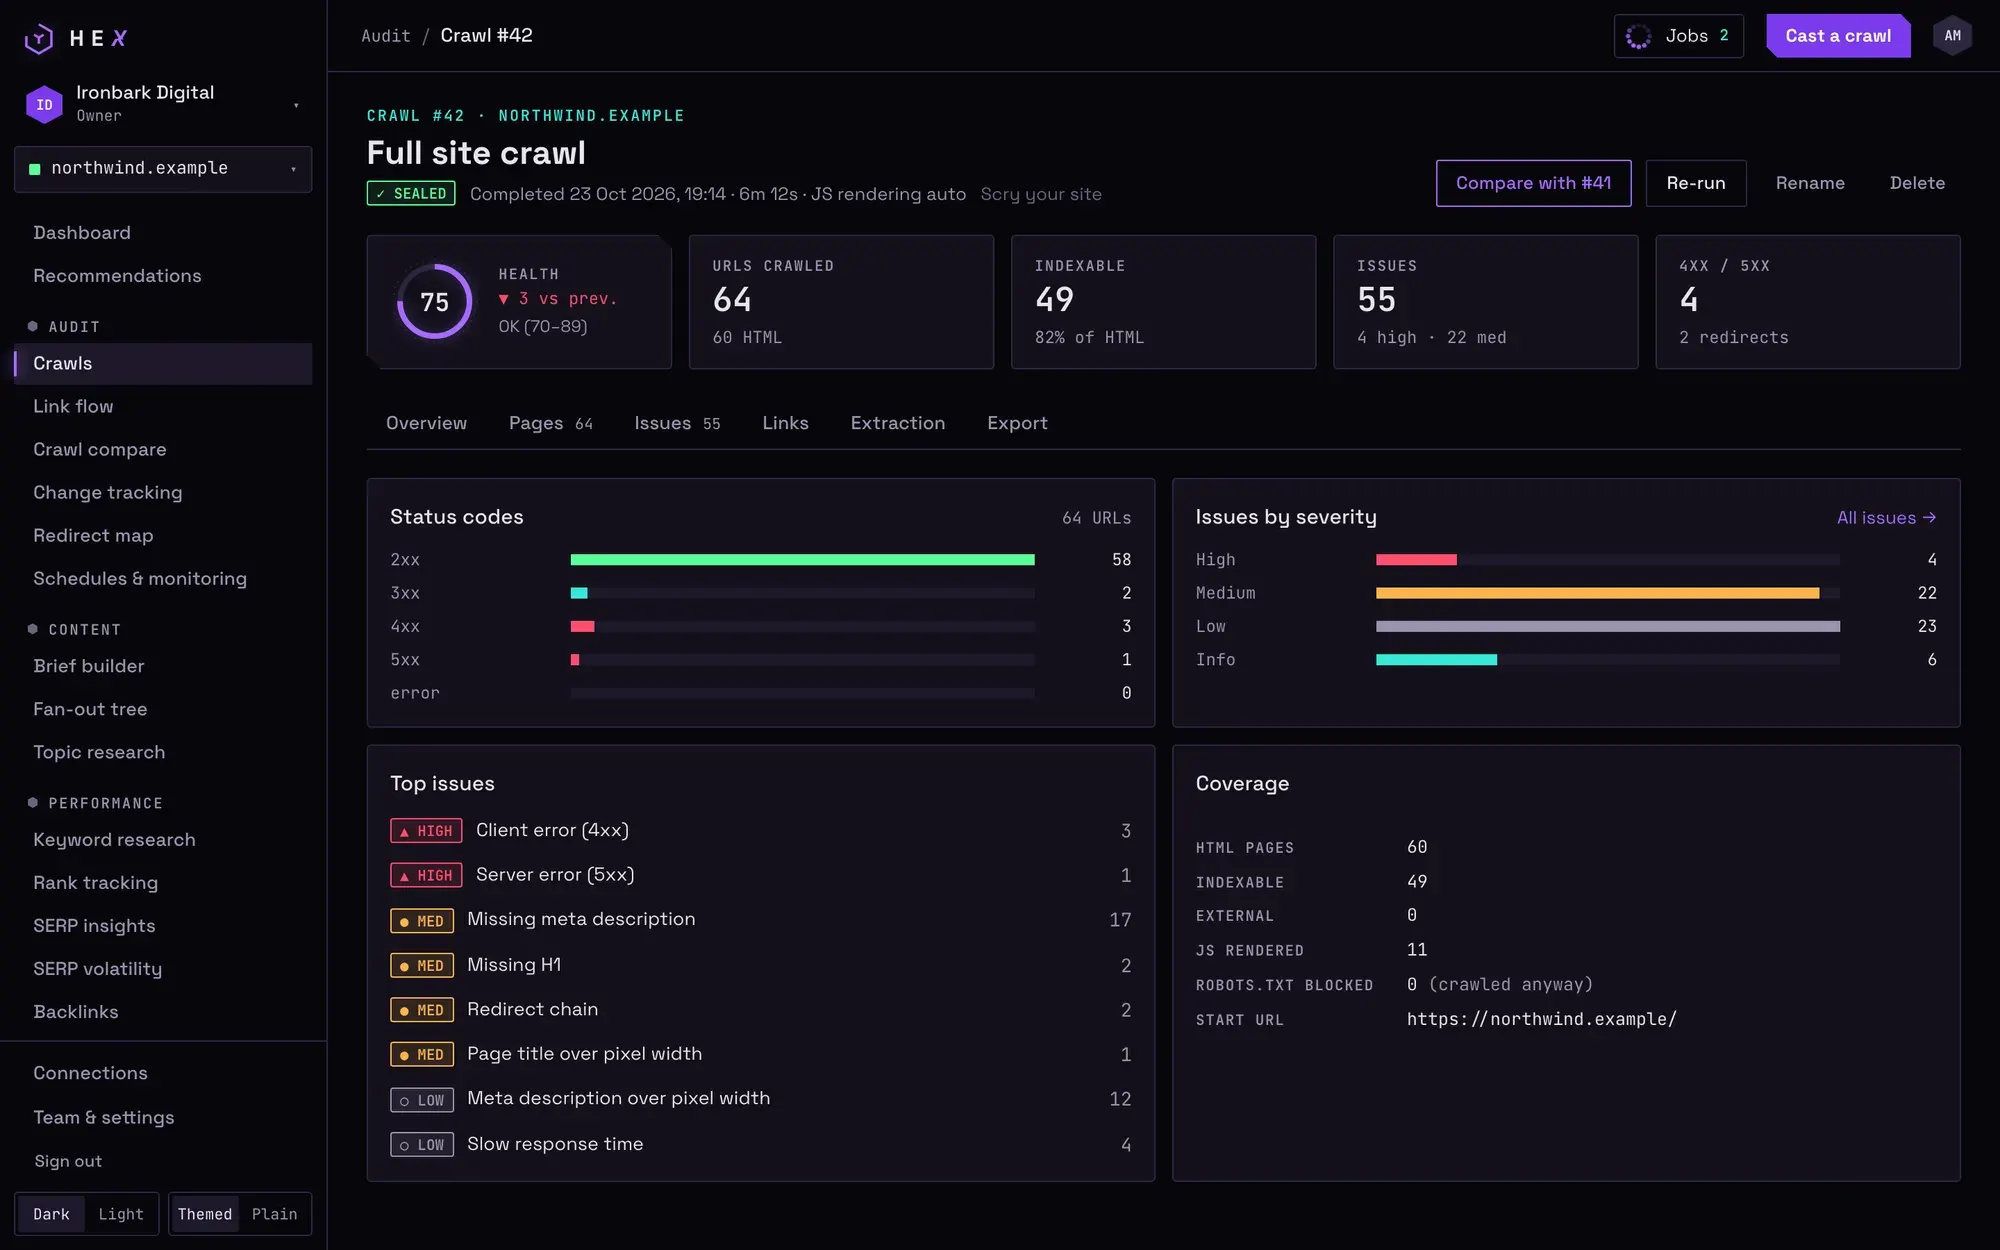
Hex crawls a site the way a search engine might, then keeps going: it renders JavaScript where it matters, measures titles in pixels, and crawls pages robots.txt would block so the problems behind them still surface.
An alternative to Screaming Frog, Sitebulb, Semrush Site Audit
What it does
JavaScript rendering where it matters
Off, on every page, or auto: auto renders app shells and thin pages only. Raw and rendered word counts are both kept, and links that only exist after rendering are marked.
robots.txt read, recorded, then ignored
Every URL records whether robots.txt would block it. Those pages are crawled anyway and flagged, so you see what search engines cannot. Switch to obeying robots.txt per crawl.
Titles and descriptions in pixels
Titles are measured against 561 px and descriptions against 985 px, with a preview of where Google would roughly cut them off.
The checks you expect
Status codes, redirect chains and loops, indexability, canonicals, duplicate and near-duplicate content, headings, alt text, hreflang, schema, orphan pages, sitemap problems, mixed content, slow and large pages.
Link flow map
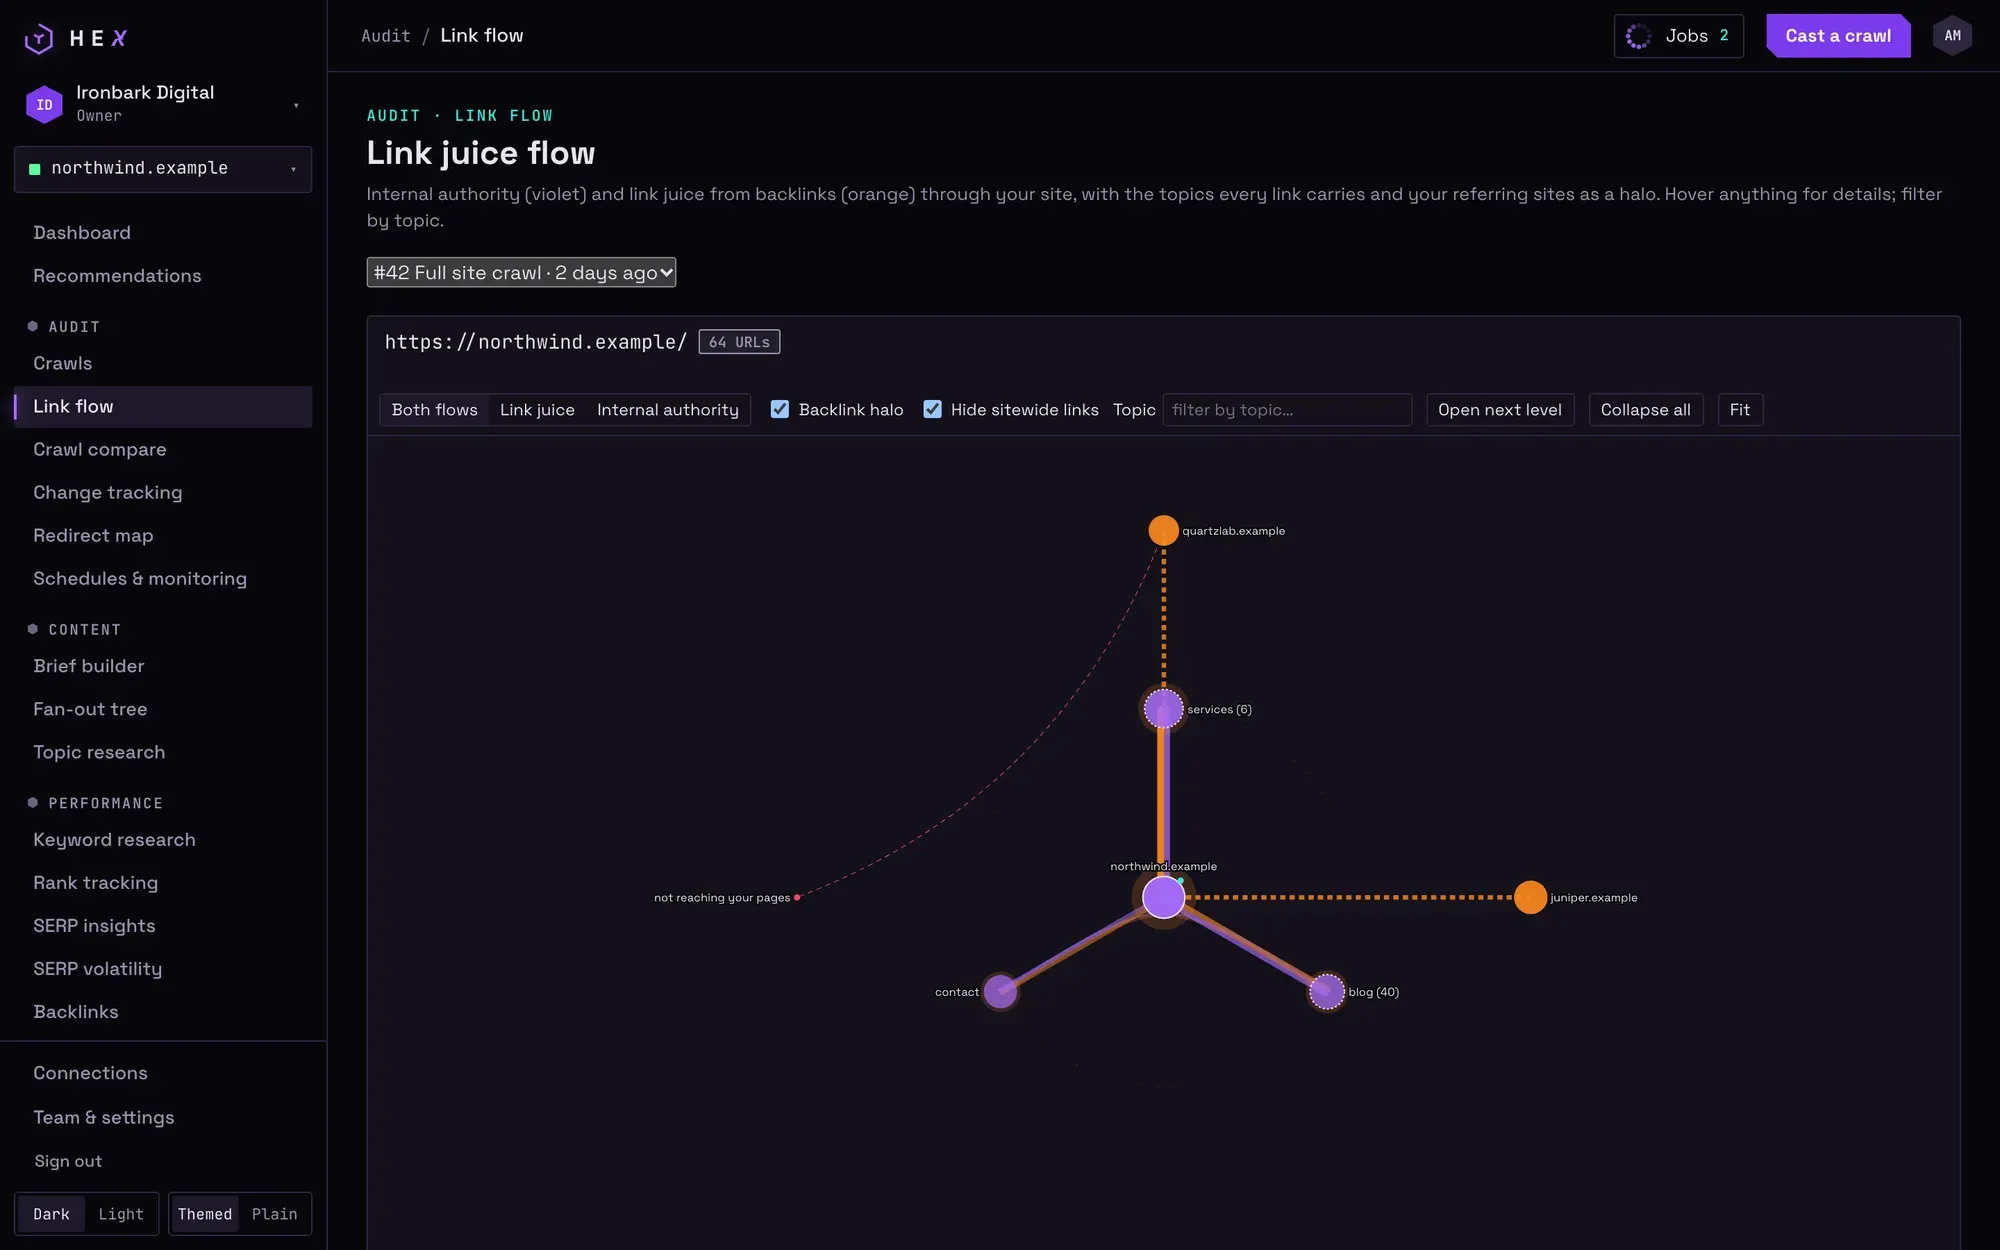
See internal authority (violet) and link equity from backlinks (orange) flow through the site, with referring domains as an outer halo and the topics each page and link carries.
Custom extraction
Pull prices, SKUs, tag IDs or element counts from every page with CSS, XPath or regex rules.
Staging sites and comparisons
Crawl behind basic auth, headers or cookies, or fetch from a staging host while recording live URLs. Compare two crawls for added, removed and changed pages and ranked regressions.
Recommendations you can apply
Issues become tasks. Dry-run them against WordPress through the Hex SEO plugin, then apply the mechanical ones: titles, descriptions, canonicals, robots, schema and redirects.
Good to know
- Rendering is slower than a plain fetch, so auto mode is the default.
- Very large sites are bounded by your plan’s crawl limits.
Questions
Does Hex obey robots.txt?
Not by default. Hex fetches robots.txt, records which URLs it would block, crawls them anyway and raises an issue on each one. You can switch to obeying robots.txt per crawl.
Can Hex crawl JavaScript sites?
Yes. Rendering can be off, automatic (app shells and thin pages only) or on for every page, and Hex flags content and links that only appear after rendering.
Is there a desktop crawler too?
Yes. Hex Desktop runs the same crawler on your own Mac or Windows PC, and can sync crawls into your Hex workspace.
More of the suite
Rank tracking
Google and Bing, locations, share of voice, AI Overview citations, dynamic tags and alert rules.
Keyword research and SERP insights
Opportunity-scored keywords, SERP clusters, keyword gaps, topic research and "why it ranks" chips.
Content briefs and scoring
Briefs from the live SERP, a 0 to 100 score with edits, and a question tree.
One workspace for every client site.
Tell us about your agency and the sites you look after, and we will send you an invitation.
Hex is in private beta: access is by invitation.